ADEEP, the Agentic Datadog Engineering Evaluation Platform, measures how well AI agents perform on Datadog-specific tasks.

Read the full board notes from the Datadog Illuminated episode “How to Evaluate AI Code against Your Company’s Standards” here: gist.github.com/wiggitywh…
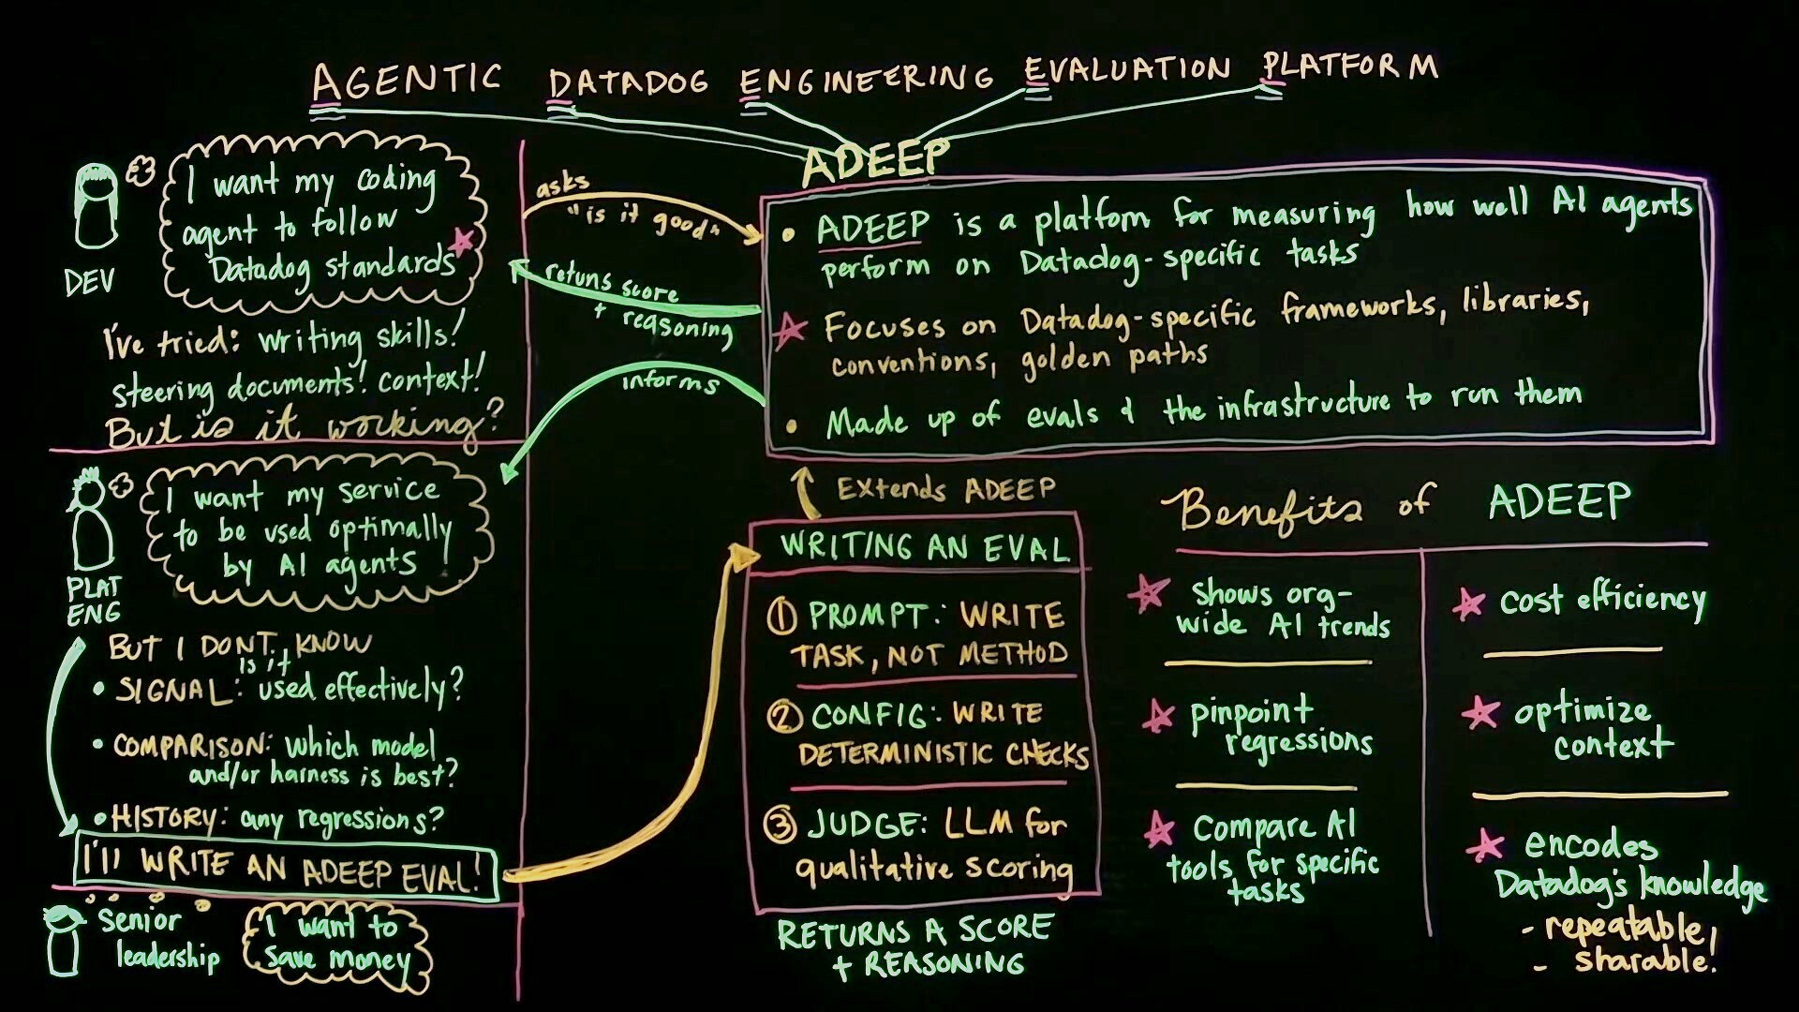
Handwritten lightboard diagram titled "AGENTIC DATADOG ENGINEERING EVALUATION PLATFORM" (ADEEP). Left side shows a developer and a platform engineer each with speech-bubble concerns about whether their coding agent follows Datadog standards and is used effectively, leading down to "I'll write an ADEEP eval!" A boxed section defines ADEEP as a platform for measuring how well AI agents perform on Datadog-specific tasks, focused on Datadog-specific frameworks, libraries, conventions, and golden paths, made up of evals and the infrastructure to run them. Arrows show a dev "asks" ADEEP "is it good," ADEEP "returns score + reasoning," and results "inform" a "Writing an Eval" box with three steps: Prompt (write task, not method), Config (write deterministic checks), and Judge (LLM for qualitative scoring), which "extends ADEEP" and returns a score and reasoning. A "Benefits of ADEEP" column lists org-wide AI trends, pinpointing regressions, comparing AI tools for specific tasks, cost efficiency, optimizing context, and encoding Datadog's knowledge in a repeatable, shareable way.